ELLIS Summer Lecture Series - Explainability & Understanding of Models
The ELLIS Lecture Series on “Explainability & Understanding of Models” brings together leading researchers to explore one of the most pressing challenges in modern AI: making complex machine learning systems transparent, interpretable, and trustworthy. As models grow in scale and impact, understanding how and why they make decisions becomes essential for scientific progress, real-world deployment, and societal acceptance. This lecture series offers cutting-edge insights into methods for explaining model behavior, uncovering internal representations, and bridging the gap between performance and interpretability—providing a platform for discussion, learning, and collaboration across the ELLIS community and beyond.
The lecture series is supported by the Professorinnenprogramm 2030 funded by the German federal and state governments as well as by the “Women in ELLIS” initiative. The Professorinnenprogramm 2030 promotes gender equality and supports the advancement of women in academia and research institutions across Germany. As part of the Professorinnenprogramm 2030, Friedrich Schiller University Jena received a positive evaluation of its gender equality concept by an independent review panel and was recognized as a “University with Strong Gender Equality” (“gleichstellungsstarke Hochschule”). “Women in ELLIS” highlights and connects leading female researchers in artificial intelligence and machine learning across Europe. Through lectures, mentoring, and networking activities, the initiative aims to strengthen diversity and female leadership in AI research.
Riestiya Zain Fadillah
Norwegian University of Science and Technology – NTNU
LECTURE DATE & TIME
November 27, 2026, 10:00 – 11:00 CET
LOCATION
Friedrich Schiller University Jena, Inselplatz 5, 07743 Jena
Letcure Hall, Room 2071
JOIN ONLINE
https://online.mmz.uni-jena.de/beta/livestream/?hsid=1113_2071
ASK YOUR QUESTIONS DURING THE LECTURE
https://eu-s.zoom.us/m/bUlxSe6XD
TITLE
Few-Shot Supervised Contrastive Learning for Image/Video Distortion Classification
ABSTRACT
Image and video processing pipelines often face distortions due to varying environments and operational conditions. In this study, a Supervised Contrastive (SupCon) framework is proposed for image and video distortion classification through the novel creation of contrastive views for the encoder to effectively learn the distortion manifold using only a limited amount of labeled data. To understand what enables the framework to learn useful distortion manifolds, we studied the components in few-shot training and evaluated the proposed framework in a cross-dataset setting. We show that (1) the proposed contrastive view and loss allows the model to learn the distortion manifold in a few-shot manner. (2) To achieve a significant improvement in classification accuracy compared to the baseline model, SupCon must be trained with a minimum of three distinct scenes. (3) The learned distortion manifold is generalizable, allowing the model to maintain its performance when evaluated on unseen scenes or variations of the distortions. By combining these findings, our proposed framework advances over prior methods that depend on supervised categorical cross-entropy, which tend to generalize poorly to unseen scenes and require substantial amounts of labeled data.
BIO
Riestiya Zain Fadillah completed her bachelor degree in 2020 from Pertamina University in Computer Science. In 2021, she completed Apple Developer Academy program, focusing on iOS app development and project management. In 2024, she graduated from the Computational Colour and Spectral Imaging (COSI), an Erasmus Mundus Joint Master Degree (EMJMD) program. The title of her work is „Expanding Optical Depth of Field (DoF) via Deep Learning Techniques in combination with Multi-colour Light“. This work was a collaboration project between COSI and COGNEX under the supervision of Dr. José Fernandez Dorado (COGNEX), Dr. Esther Oteo Lozano (COGNEX), and Prof. Javier Hernández Andrés (University of Granada). Prior to joining NTNU as a PhD candidate, she was employed as a Machine Learning Engineer at Gringgo. Her research focuses on inverse problems in imaging, with particular focus on image and video quality assessment and enhancement, and developing efficient machine learning methods.
Simone Schaub-Meyer
Technical University of Darmstadt
LECTURE DATE & TIME
July 8, 2026, 16:00 – 17:00
LOCATION
Friedrich Schiller University Jena, Inselplatz 5, 07743 Jena
Letcure Hall, Room 005
TITLE
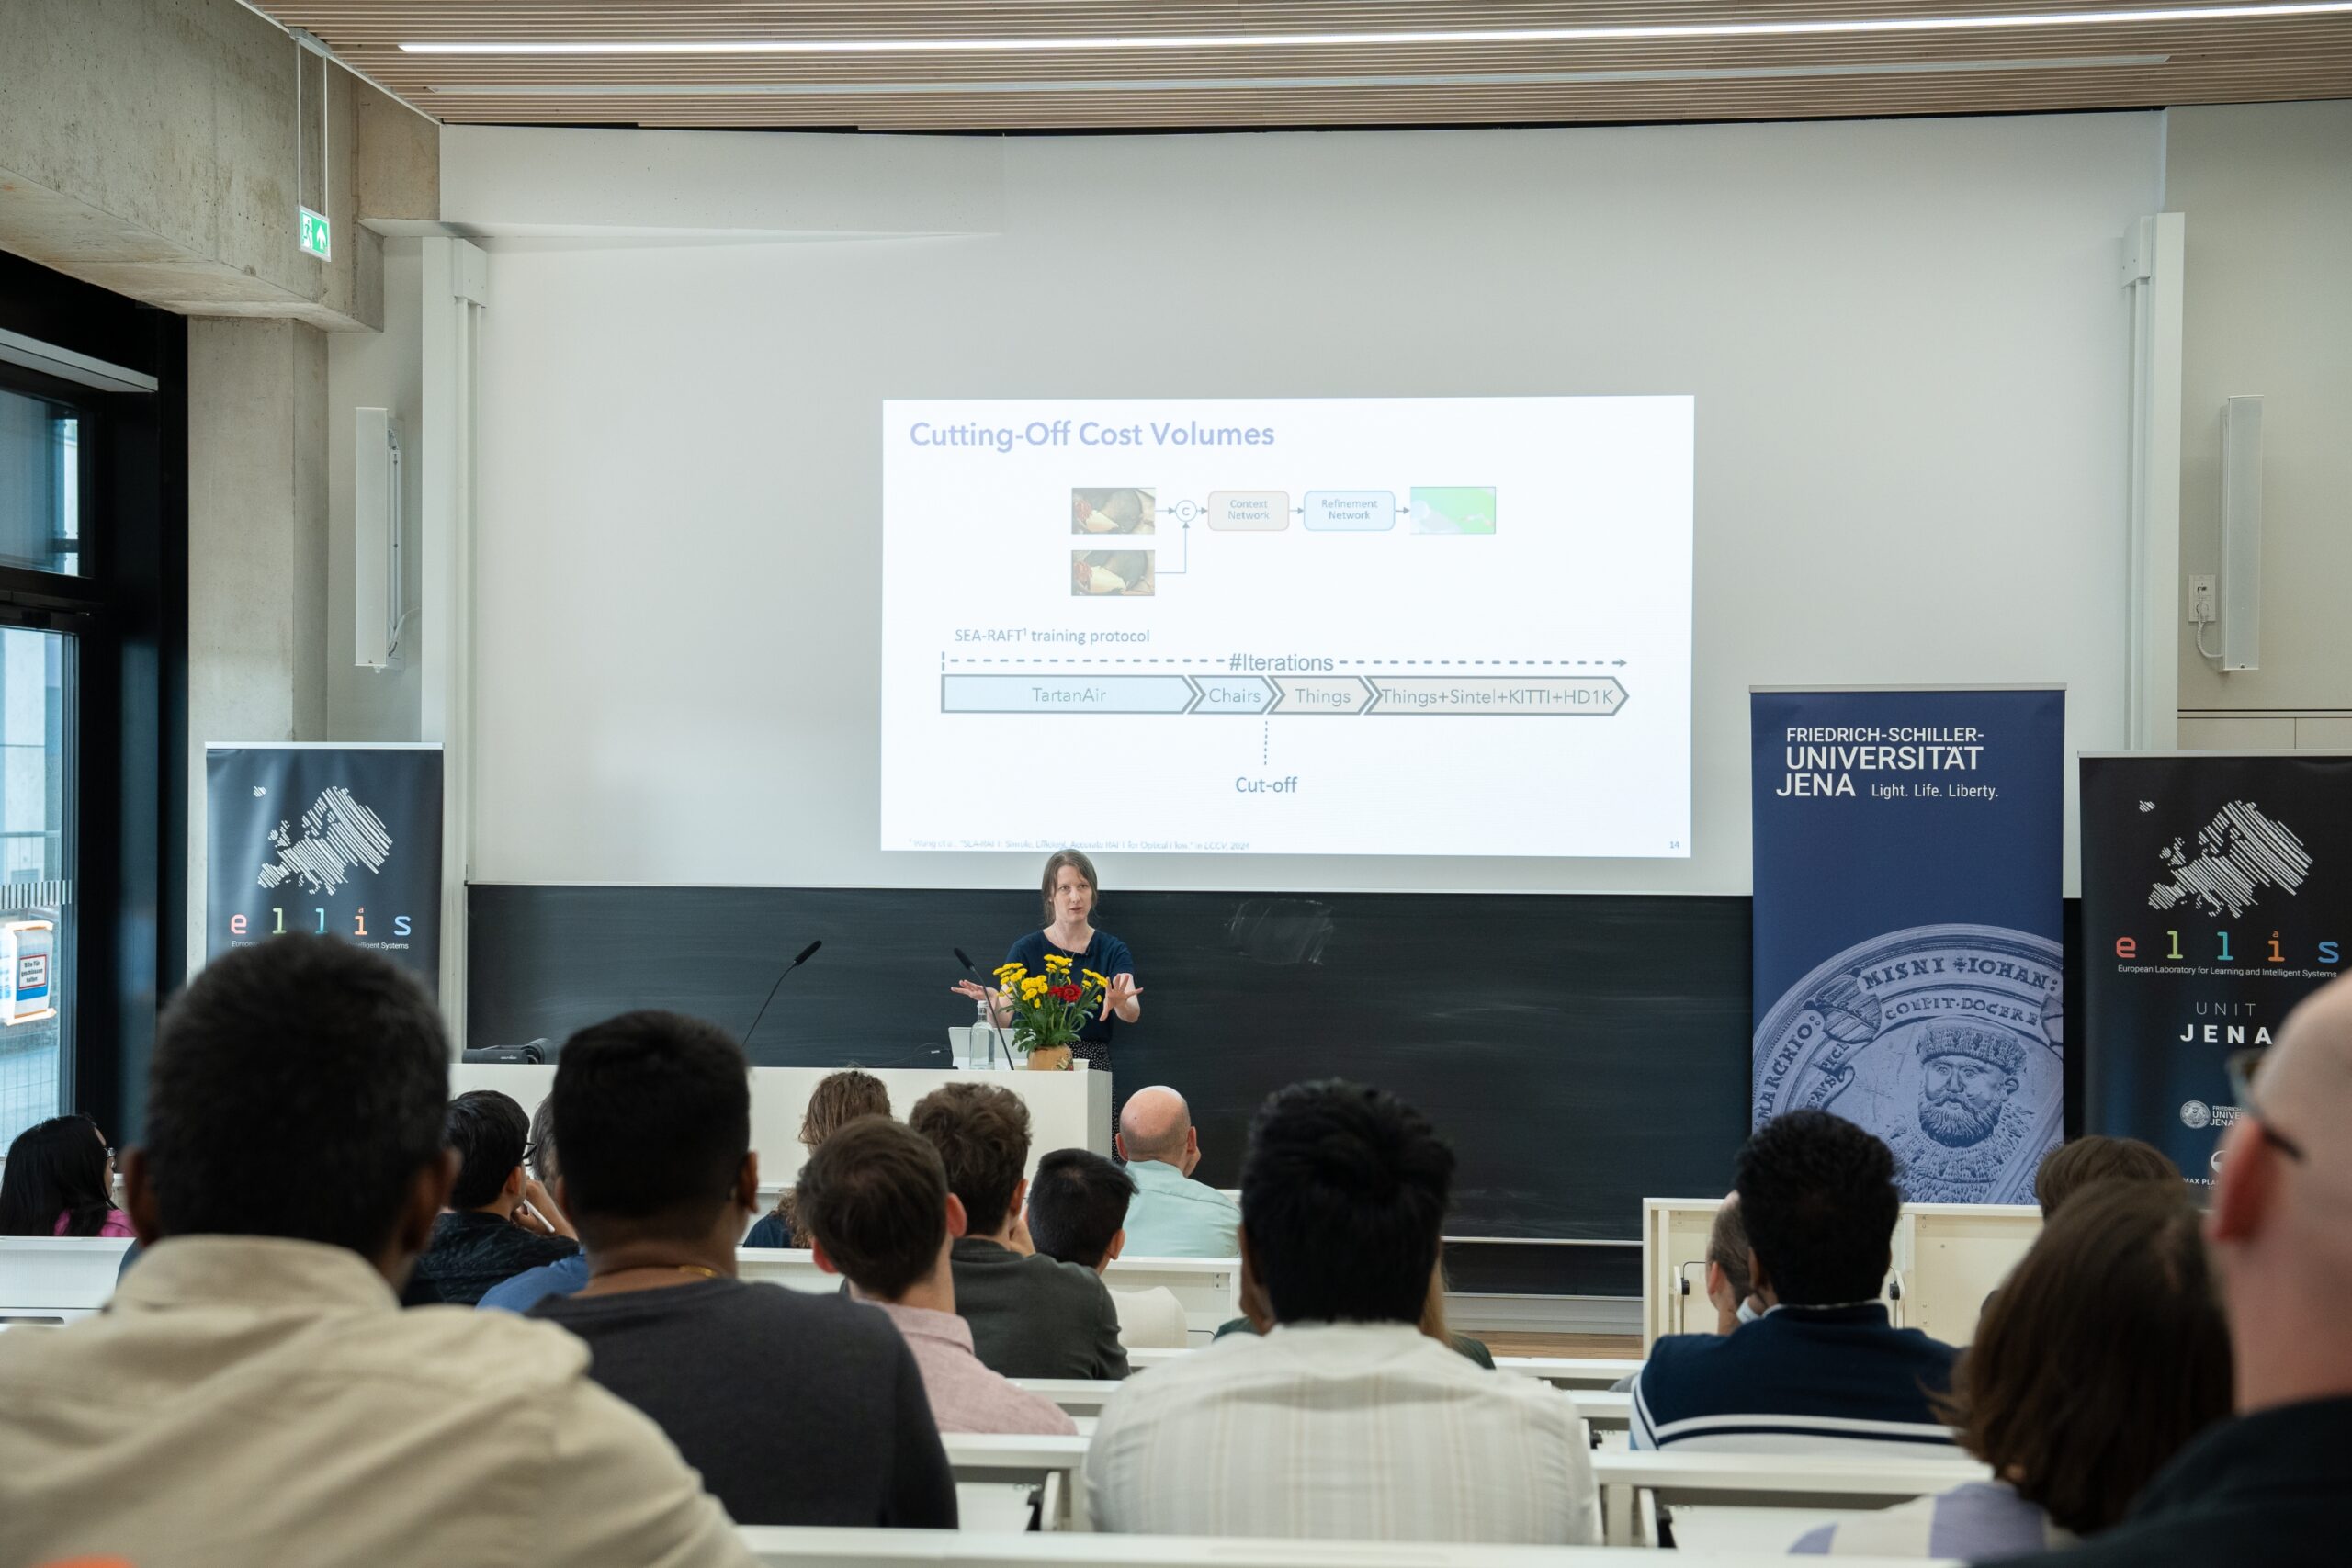
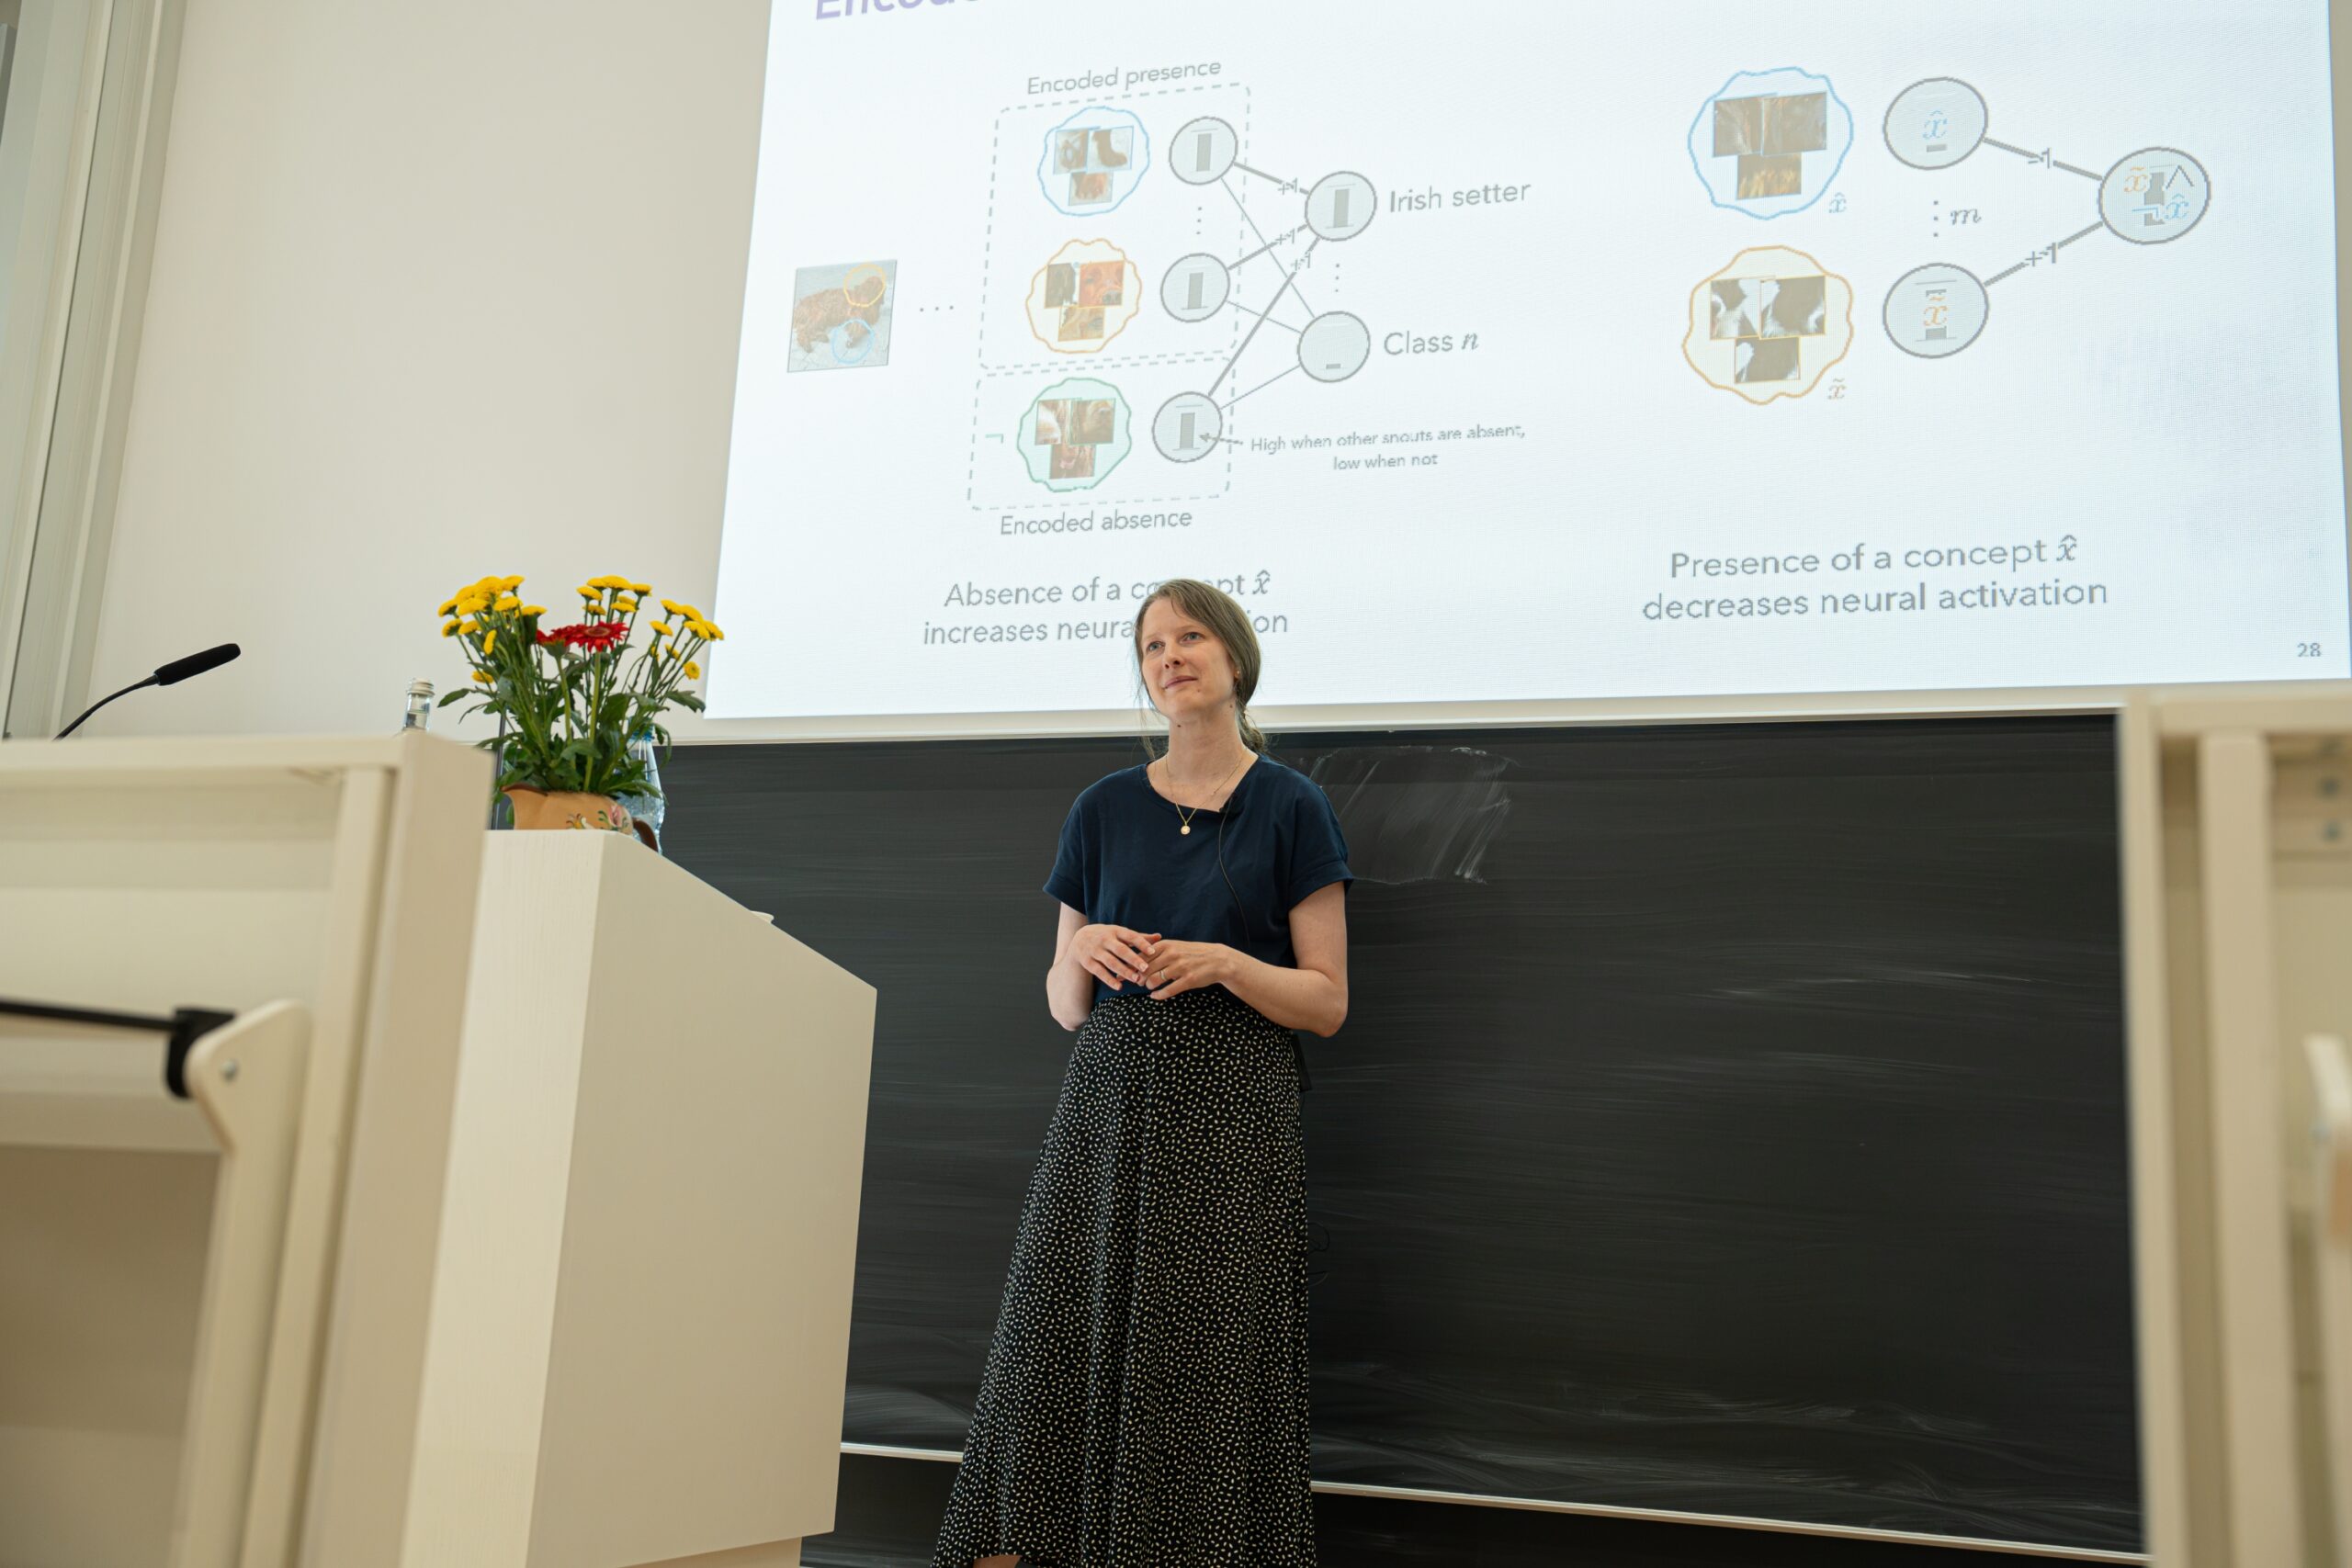
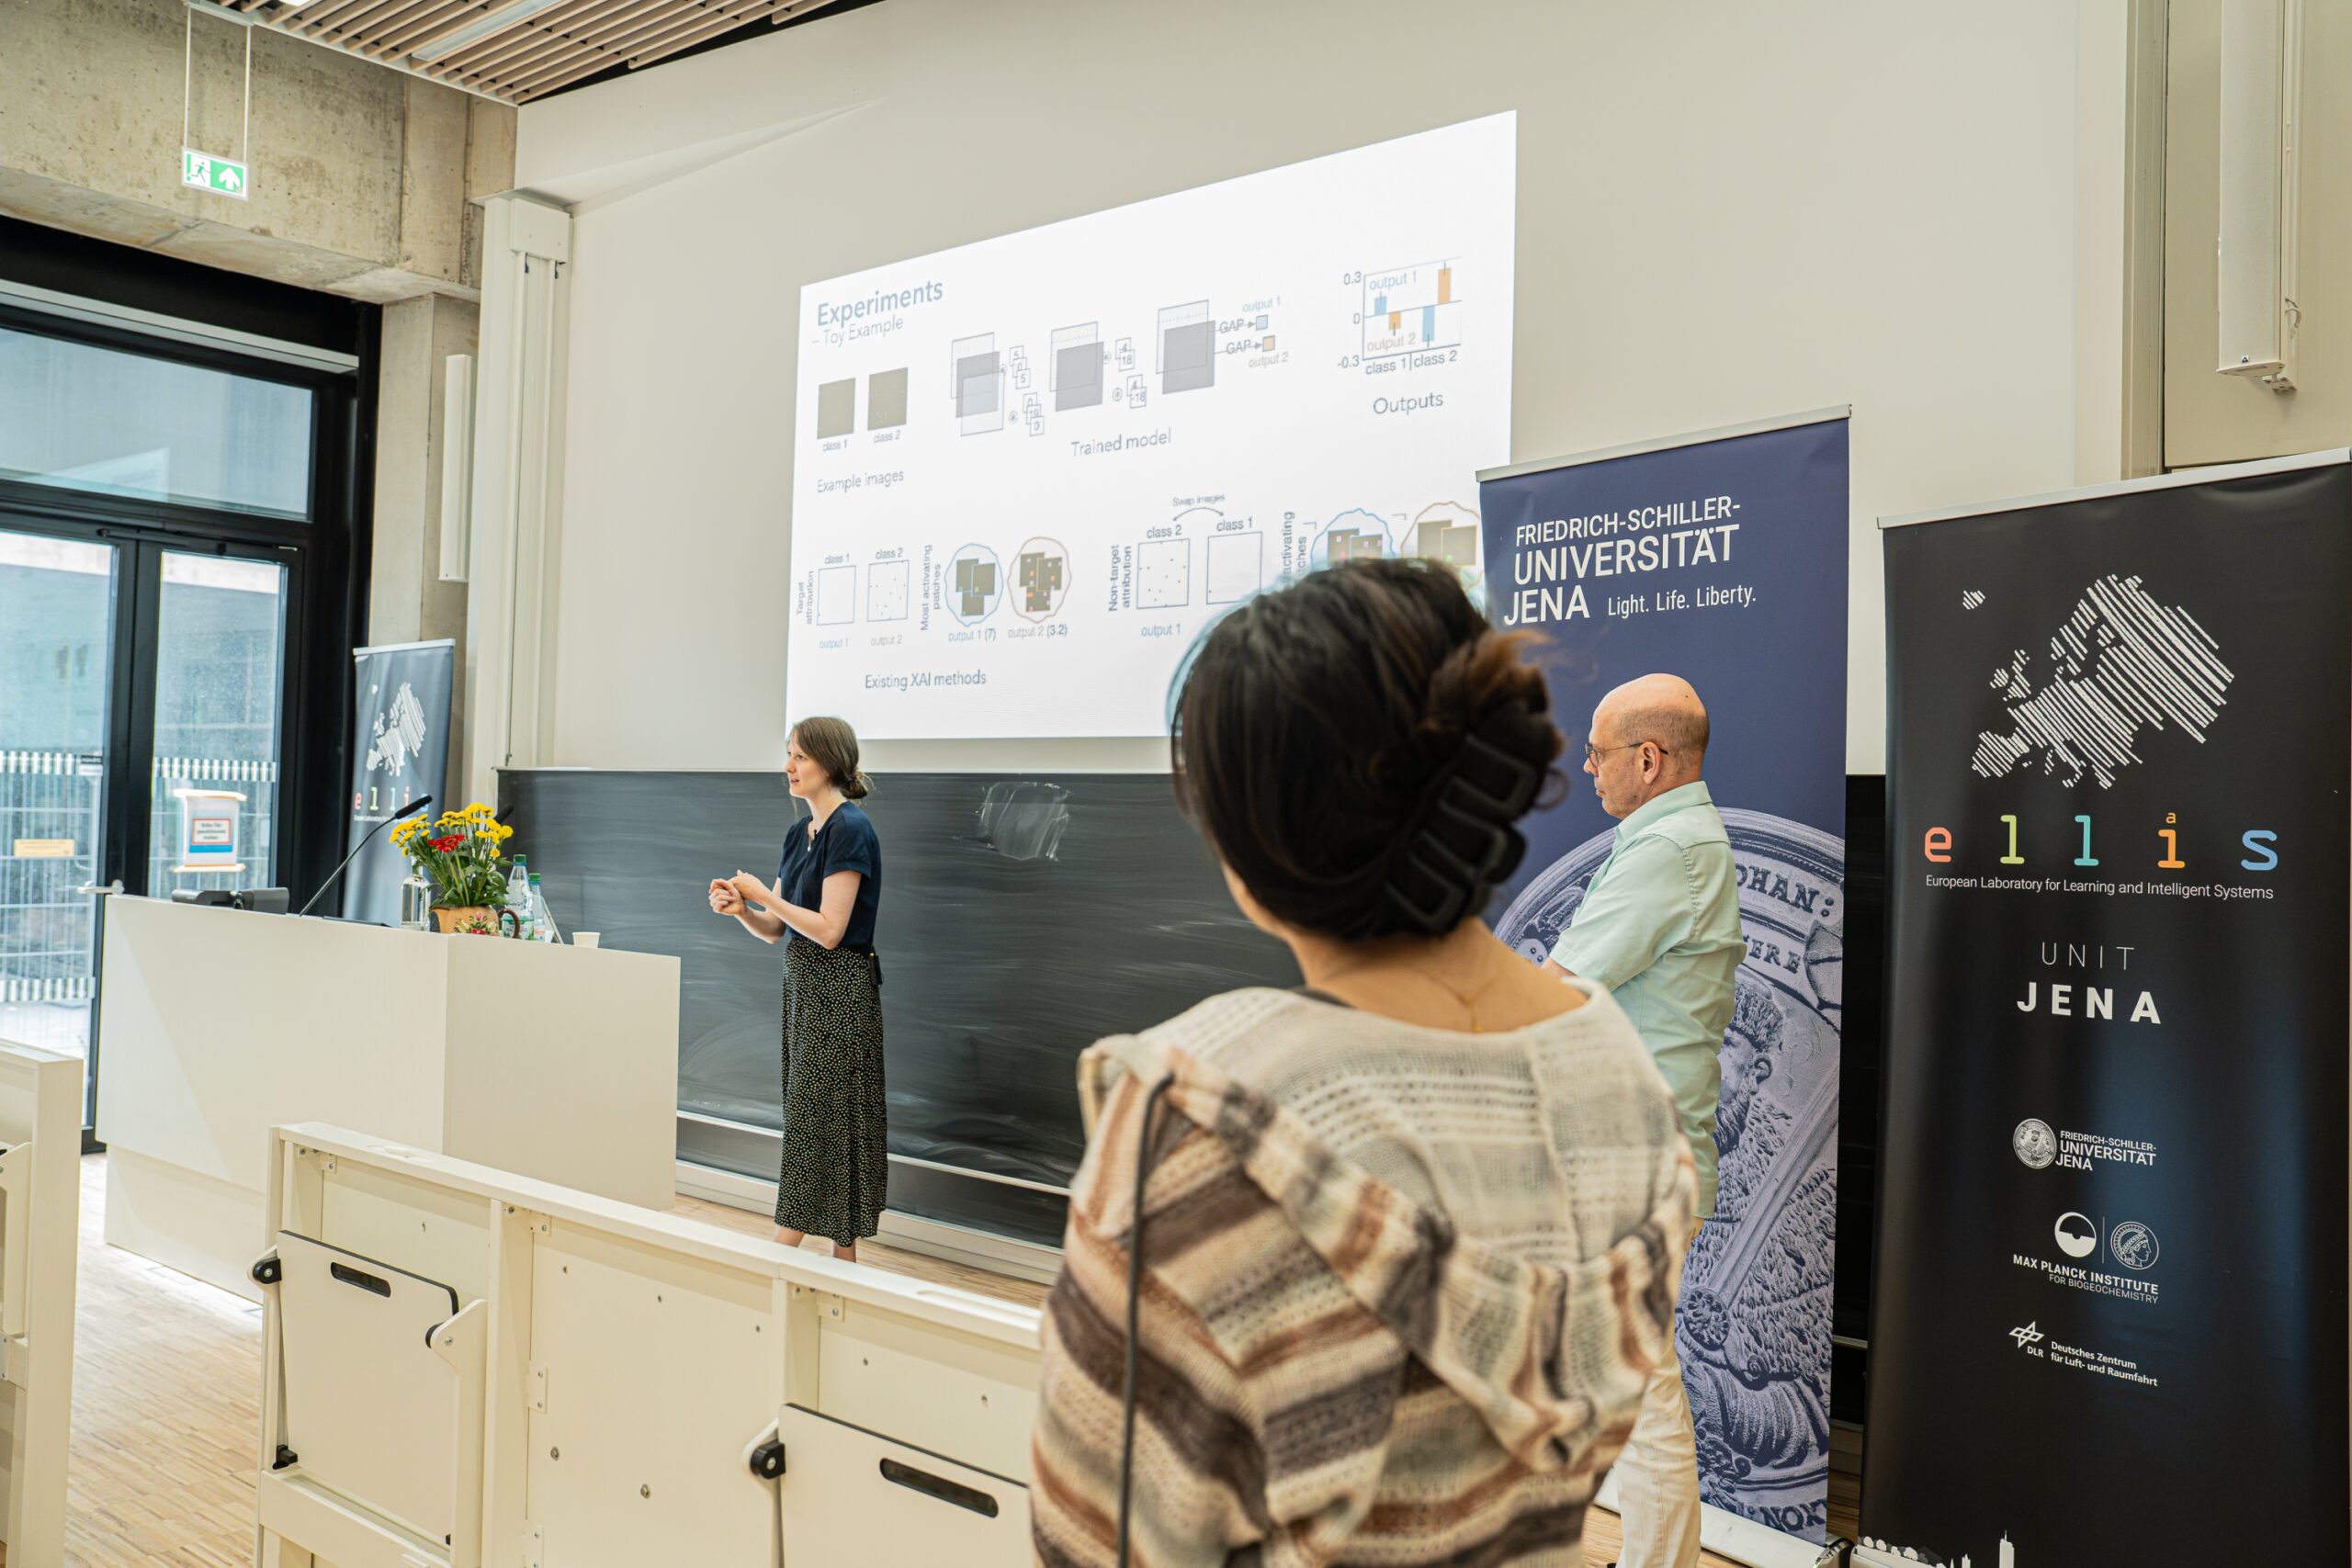
Understanding Deep Vision Models and Its Benefits
ABSTRACT
Deep learning has led to remarkable progress in computer vision, yet benchmark accuracy alone provides only a limited view of model capabilities. In this talk, I will argue that a deeper analysis of model behavior can yield both practical improvements and conceptual insights. First, I will show how fine-grained performance analyses can lead towards simpler and more computationally efficient vision models. In the second part, I will focus on understanding model behavior through visual explanations. I will discuss the role of visual explanations in improving classification and present a method to obtain such explanations efficiently in
practice. I will then highlight recent findings showing that deep networks rely not only on the presence of visual concepts, but also on their absence and show how extending attribution and feature visualization methods makes these effects visible. Together, these perspectives illustrate how a deeper understanding of model behavior can inform the design of more efficient, reliable, and interpretable vision models.
BIO
Simone Schaub-Meyer leads a research group on image and video analysis at the
Technical University of Darmstadt. Her work focuses on developing efficient, robust, and interpretable methods for visual perception Her research is supported by the Emmy Noether Programme of the German Research Foundation. Assistant Professor Schaub-Meyer is a member of the ELLIS Unit Darmstadt and the Hessian Center for Artificial Intelligence (hessian.AI). She received her doctoral degree from ETH Zurich in collaboration with Disney Research Zurich, where her thesis on motion representation and video frame interpolation was awarded the ETH Medal.
URL
https://www.visinf.tu-darmstadt.de/visual_inference/people_vi/visinf_team_details_102784.en.jsp
Margret Keuper
University of Mannheim, Max Planck Institute for lnformatics
LECTURE DATE & TIME
June 24, 2026, 16:00 – 17:00
LOCATION
Friedrich Schiller University Jena, Inselplatz 5, 07743 Jena
Letcure Hall, Room 005
TITLE
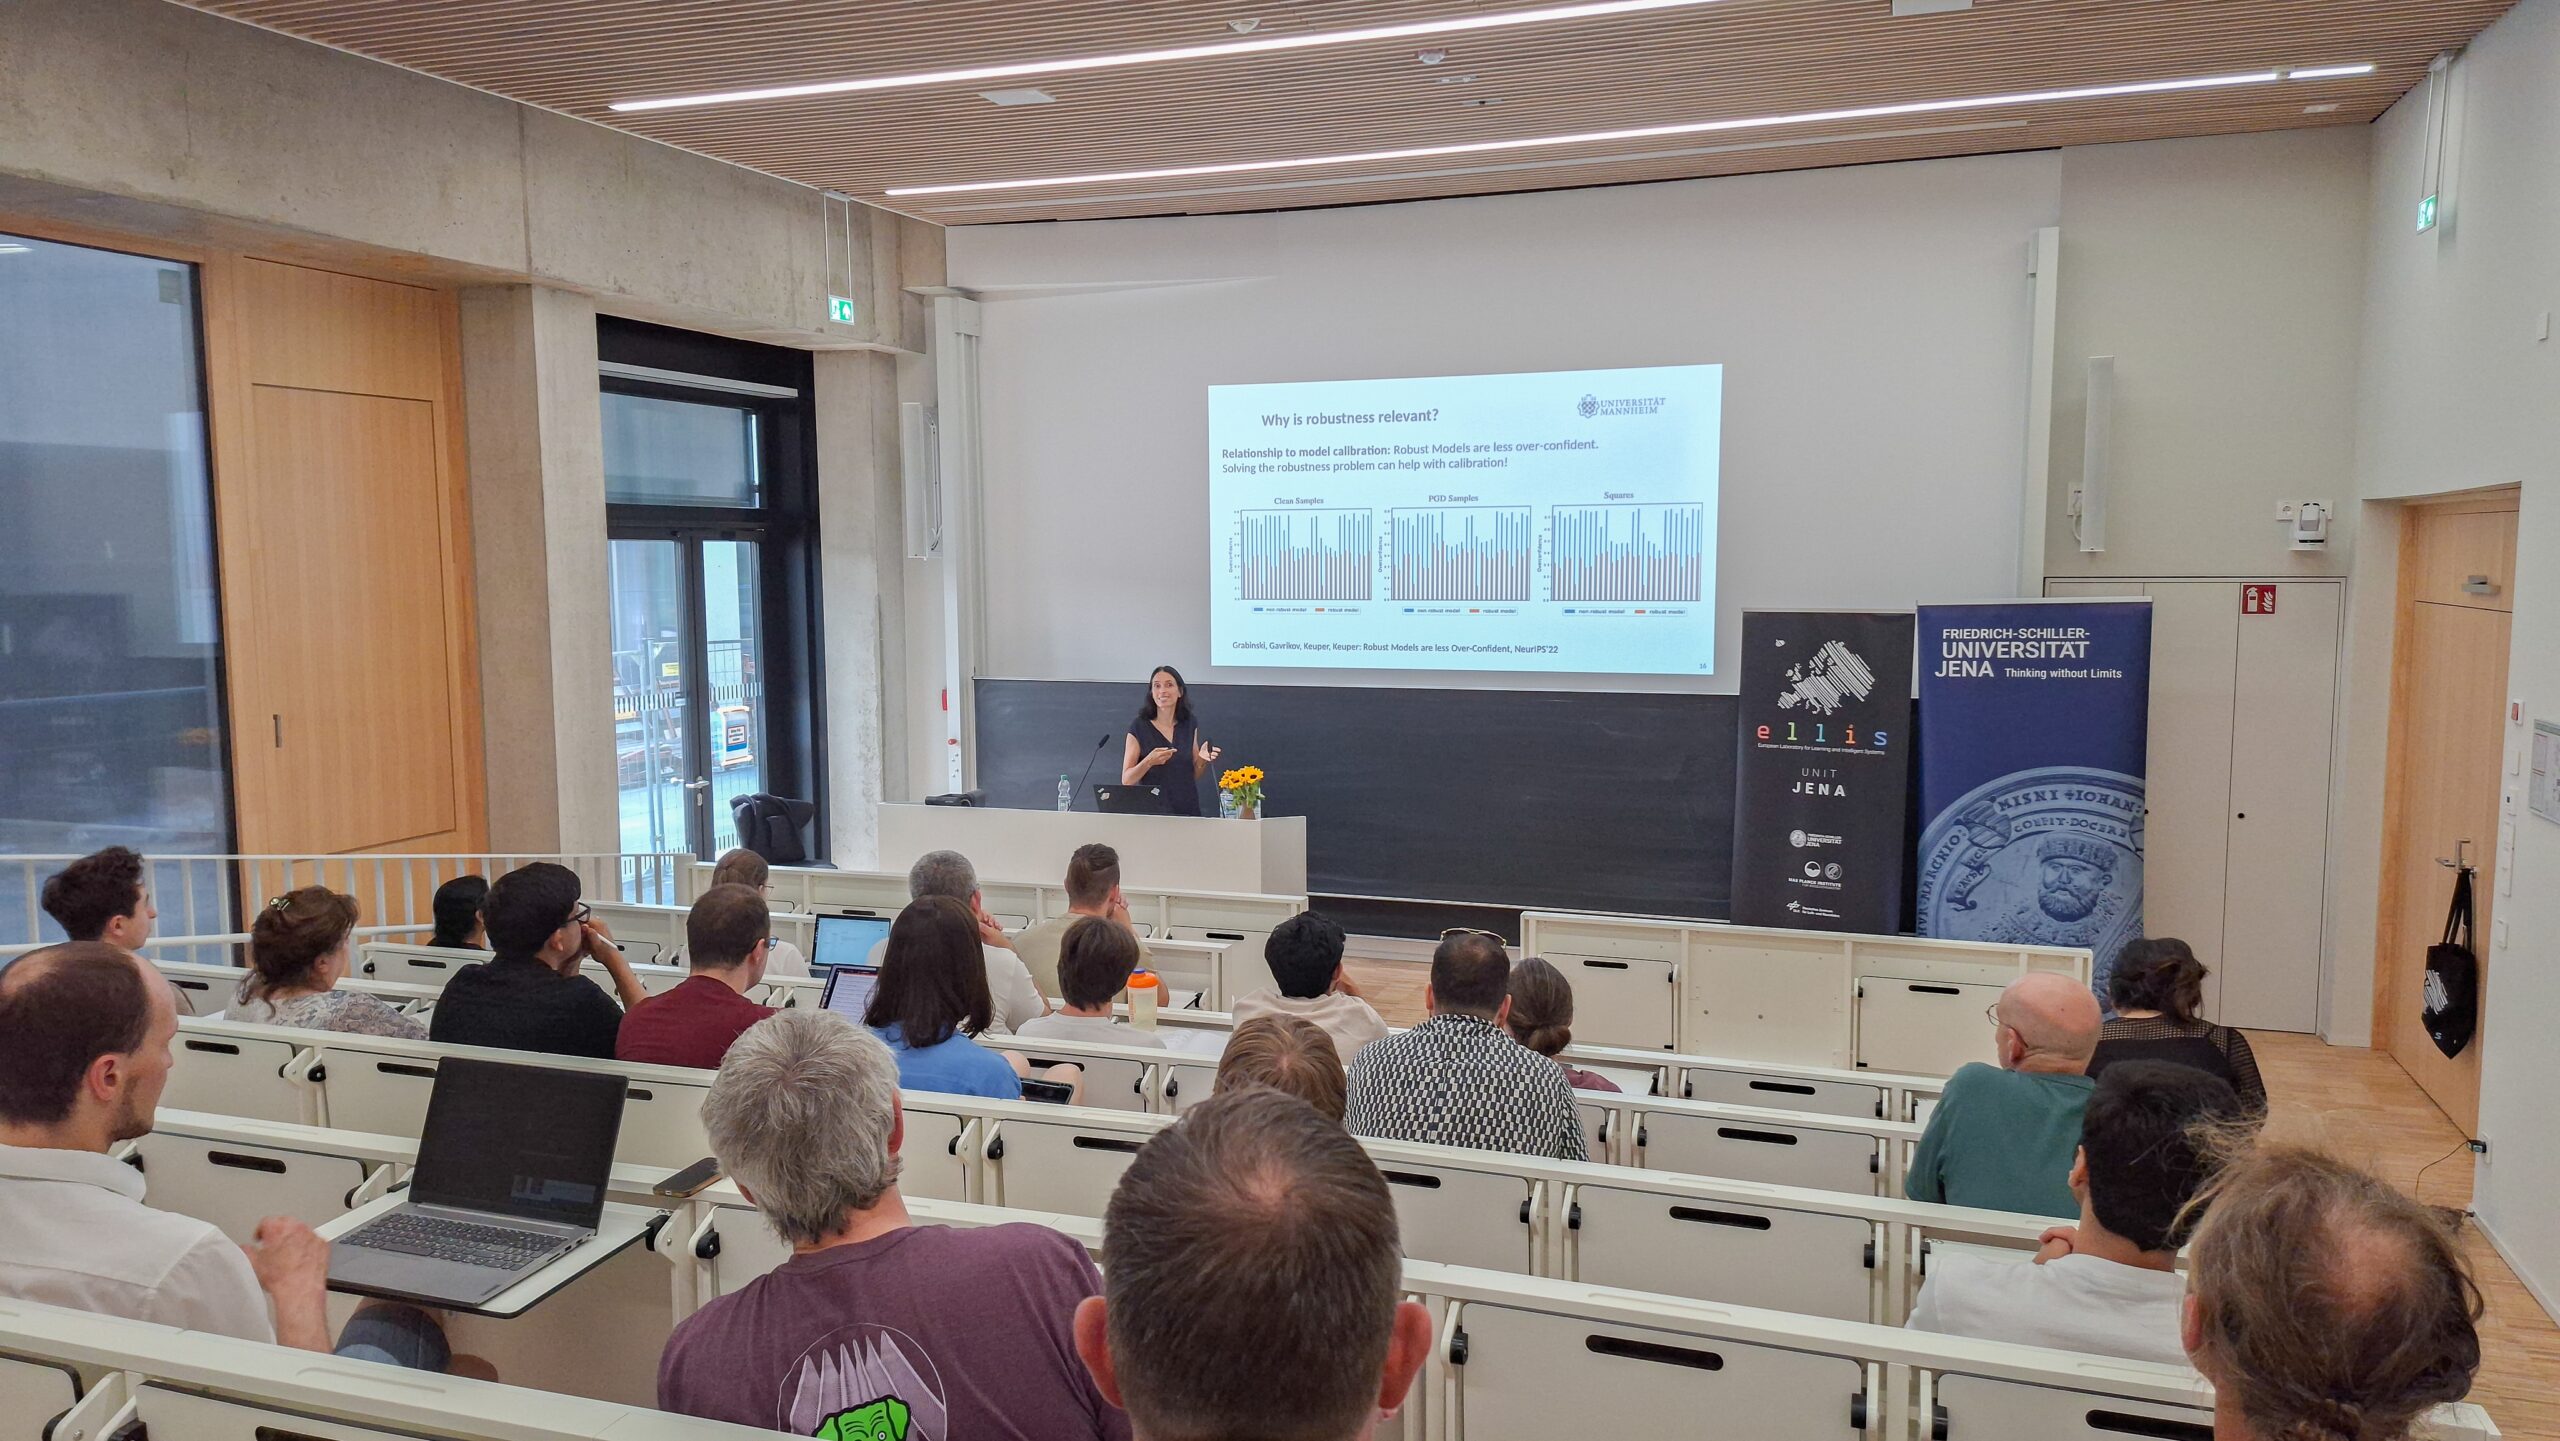
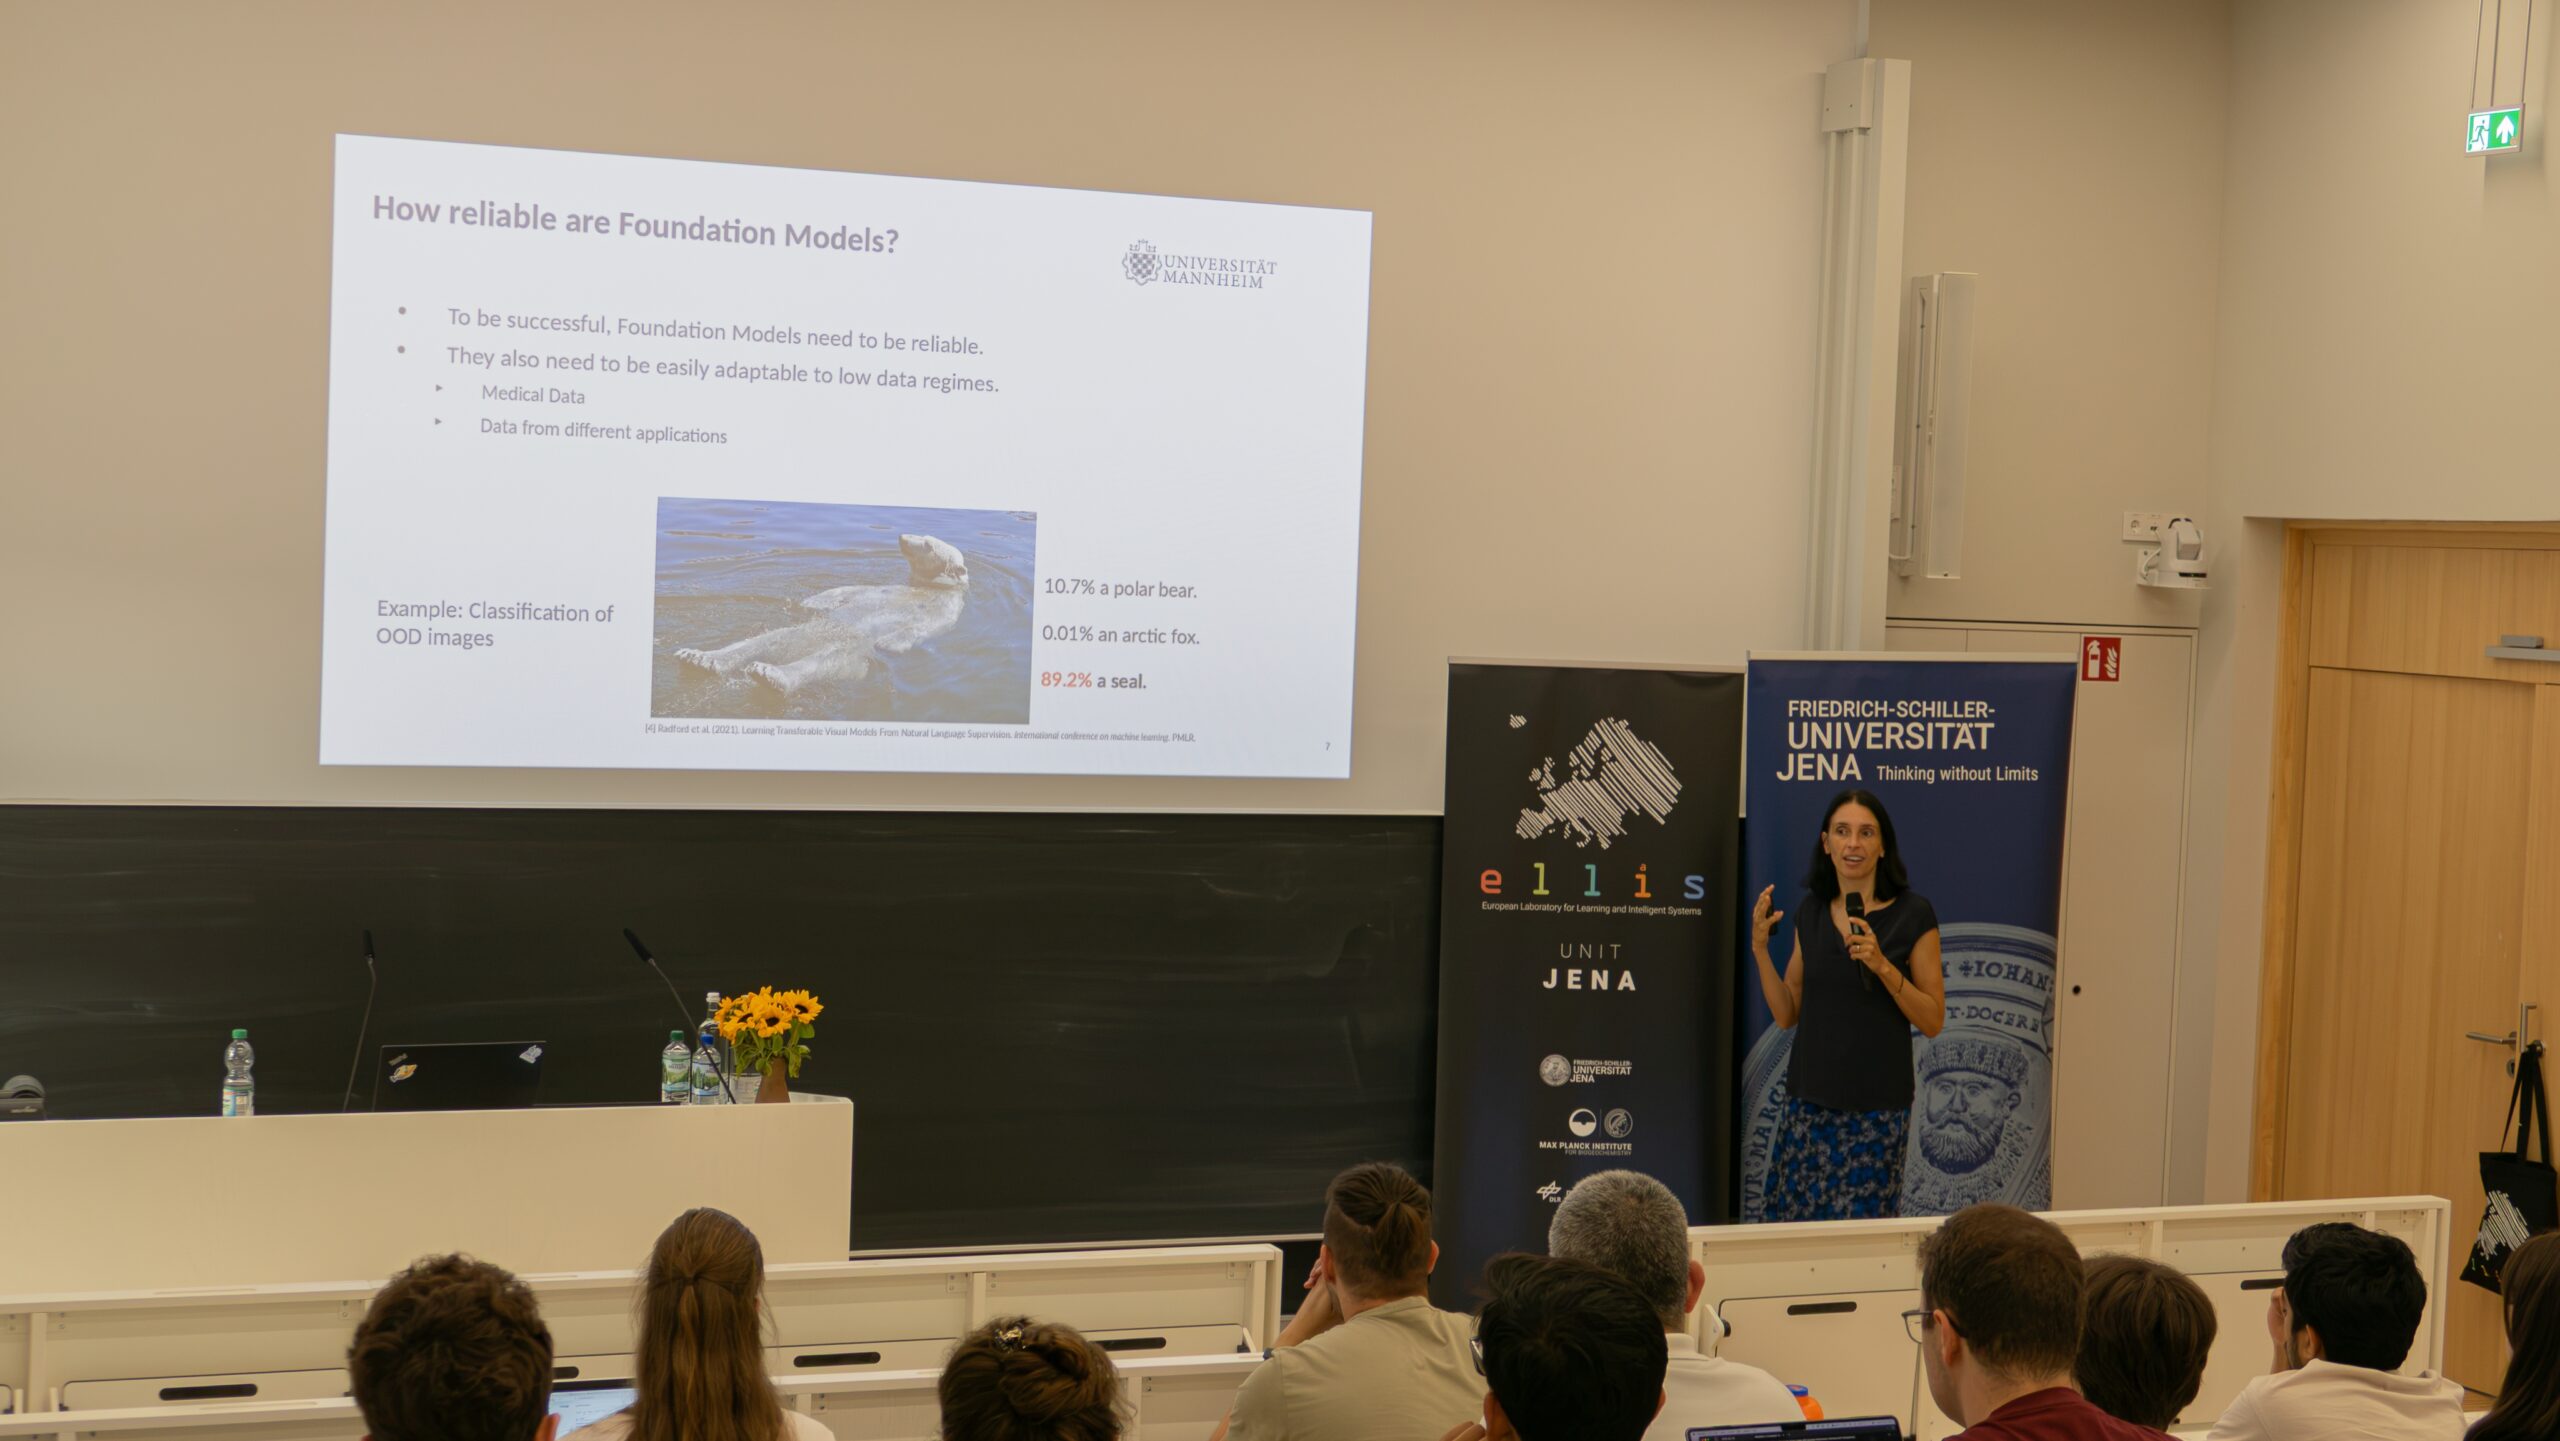
Reliablility in Computer Vision – Trade-Offs between Robustness, Fairness and Transparency
ABSTRACT
Prof. Dr. Margret Keuper’s research focuses on making machine learning and computer vision systems more reliable, robust, and transparent. While recent advances in AI have been driven by the availability of large datasets, increased computational resources, and highly specialized learning architectures, many current models still struggle with limited explainability, poor generalization to new environments, and vulnerability to adversarial attacks.
In her work, Prof. Keuper investigates methods that improve the robustness of machine learning models under domain shifts and adversarial perturbations while also addressing fairness-related challenges. Another key focus of her research is understanding the relationship between model interpretability and spurious correlations, with the goal of developing AI systems that are not only accurate but also trustworthy and transparent. Her research contributes to advancing the practical applicability of machine learning in real-world settings where reliability and accountability are essential.
[1] S. Agnihotri, S. Jung, M. Keuper, CosPGD: A unified white-box adversarial attack for pixel-wise prediction tasks, ICML 2024.
[2] Fair-TAT: Improving Model Fairness Using Targeted Adversarial Training, T. Medi, S. Jung,M. Keuper, Winter Conference on Computer Vision (WACV) 2025.
[3] Maxsup: Overcoming representation collapse in label smoothing, Y. Zhou, H. Li, Z.Q. Cheng, X. Yan, Y. Dong, M .Fritz, M. Keuper, Advances in Neural Information Processing Systems (NeurIPS), 2025 (oral).
[4] AIM: Amending Inherent Interpretability via Self-Supervised Masking, E. Alshami, S. Agnihotri, B. Schiele, M. Keuper, International Conference on Computer Vision (ICCV) 2025.
[5] DCBM: Data-Efficient Visual Concept Bottleneck Models, K. Prasse, P. Knab, S. Marton, C. Bartelt, M. Keuper, International Conference on Machine Learning (ICML) 2025.
BIO
Prof. Dr. Margret Keuper is a full professor for Machine Learning with focus on computer vision at the University of Mannheim. She is also an affiliated research leader at the Max Planck Institute for Informatics, Saarbrücken. Professor Keuper received her PhD degree from the University of Freiburg under the supervision of Prof Thomas Brox and worked as a postdoctoral researcher at the University of Freiburg working on topics related to motion estimation, segmentation, and grouping. Since 2024 Professor Keuper is a ELLIS Fellow and member oft he ELLIS Unit Saarbrücken.
URL
https://www.uni-mannheim.de/dws/people/professors/prof-dr-ing-margret-keuper/
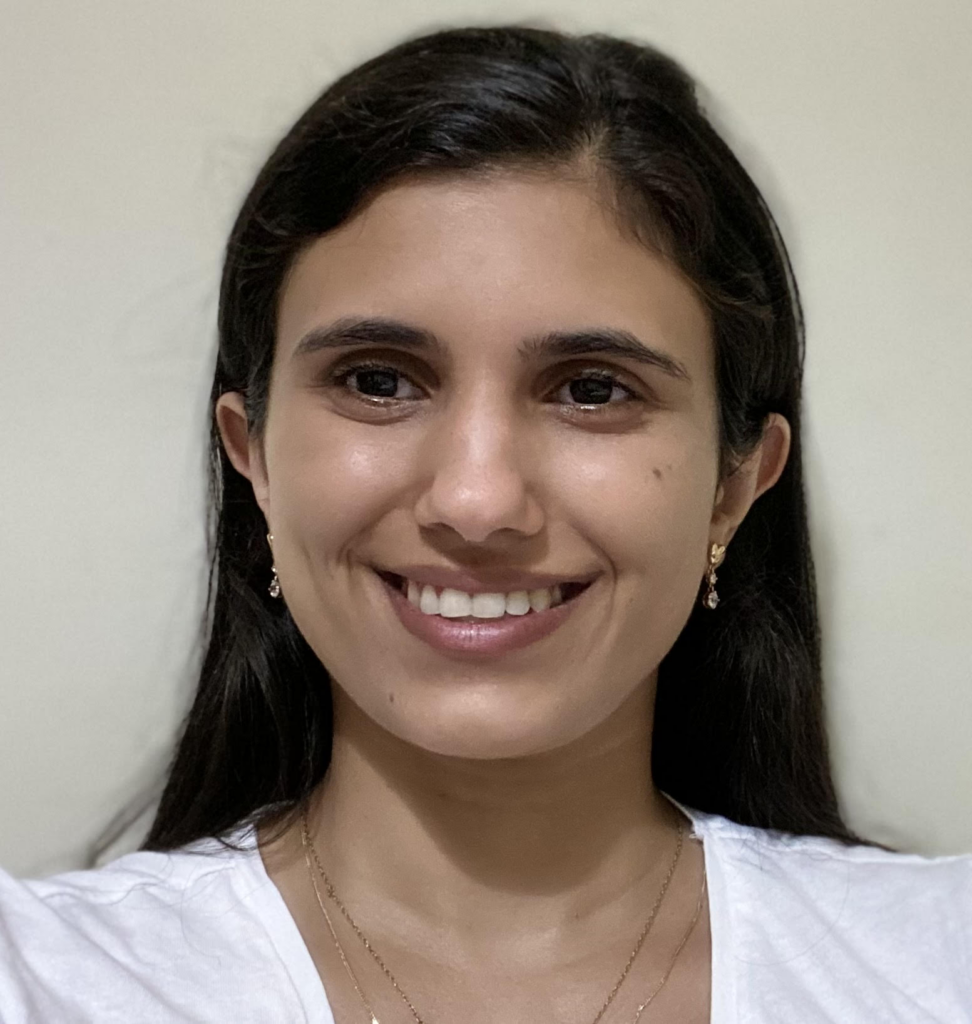
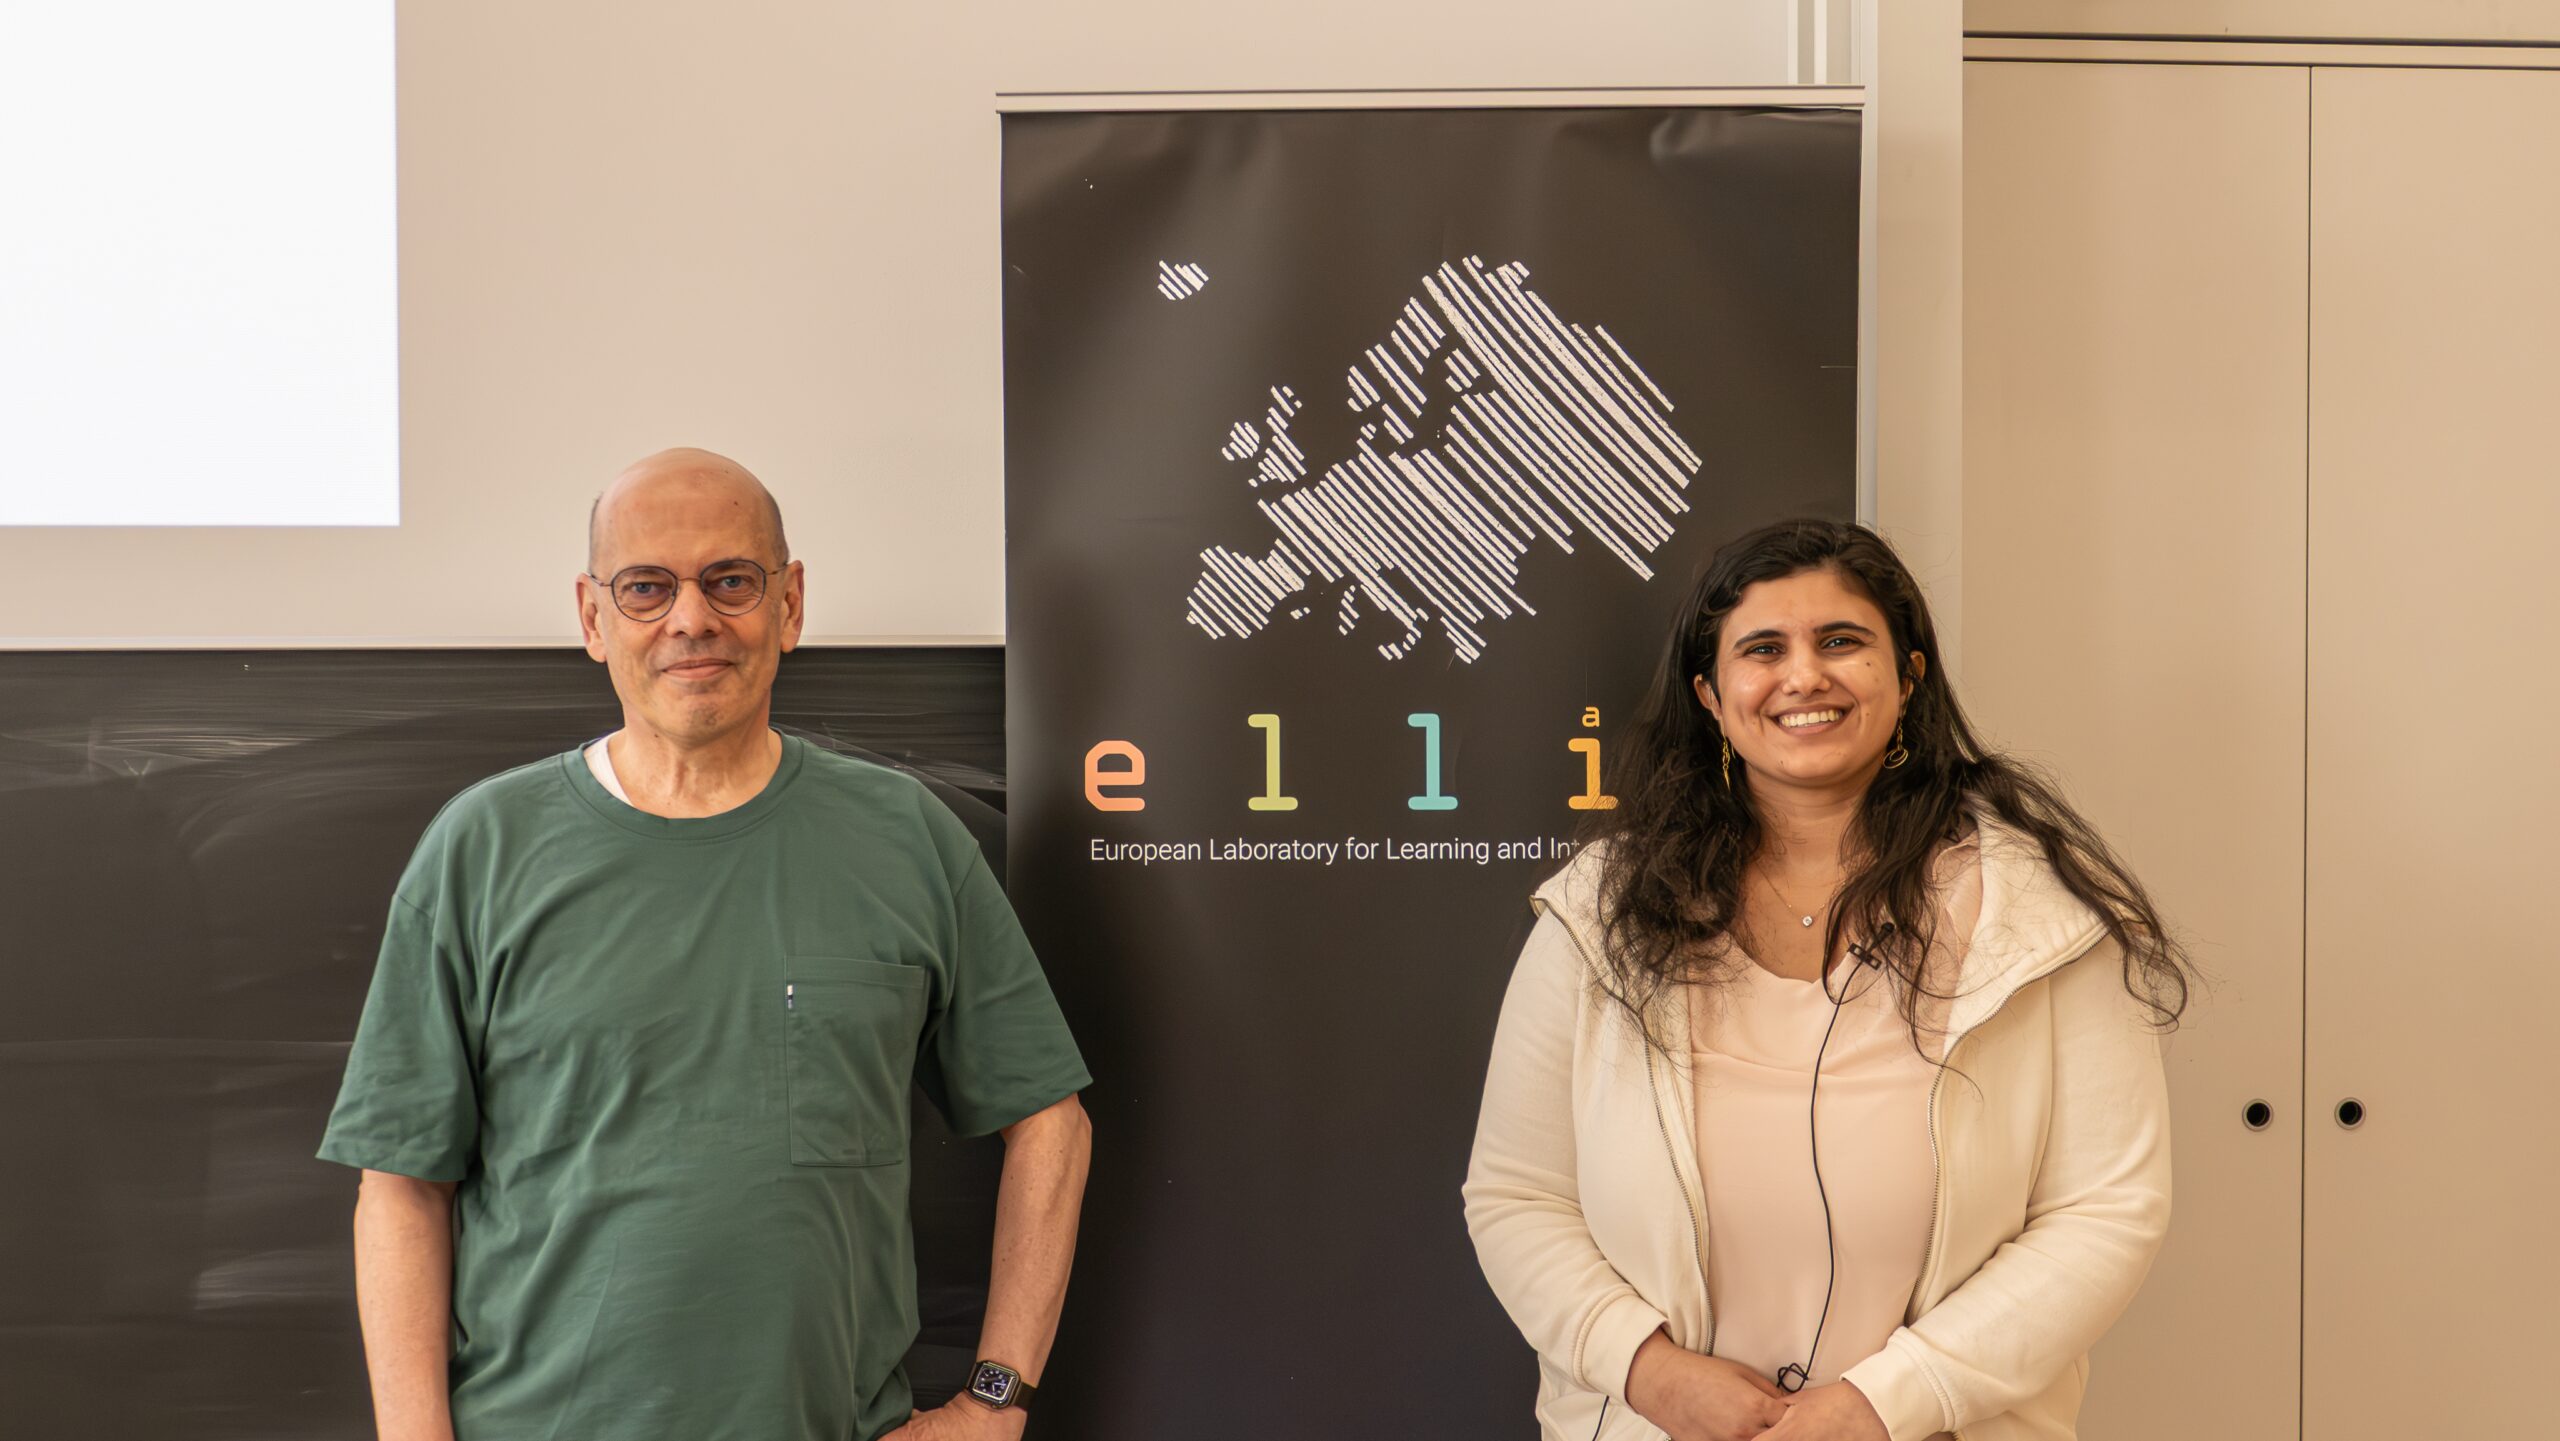
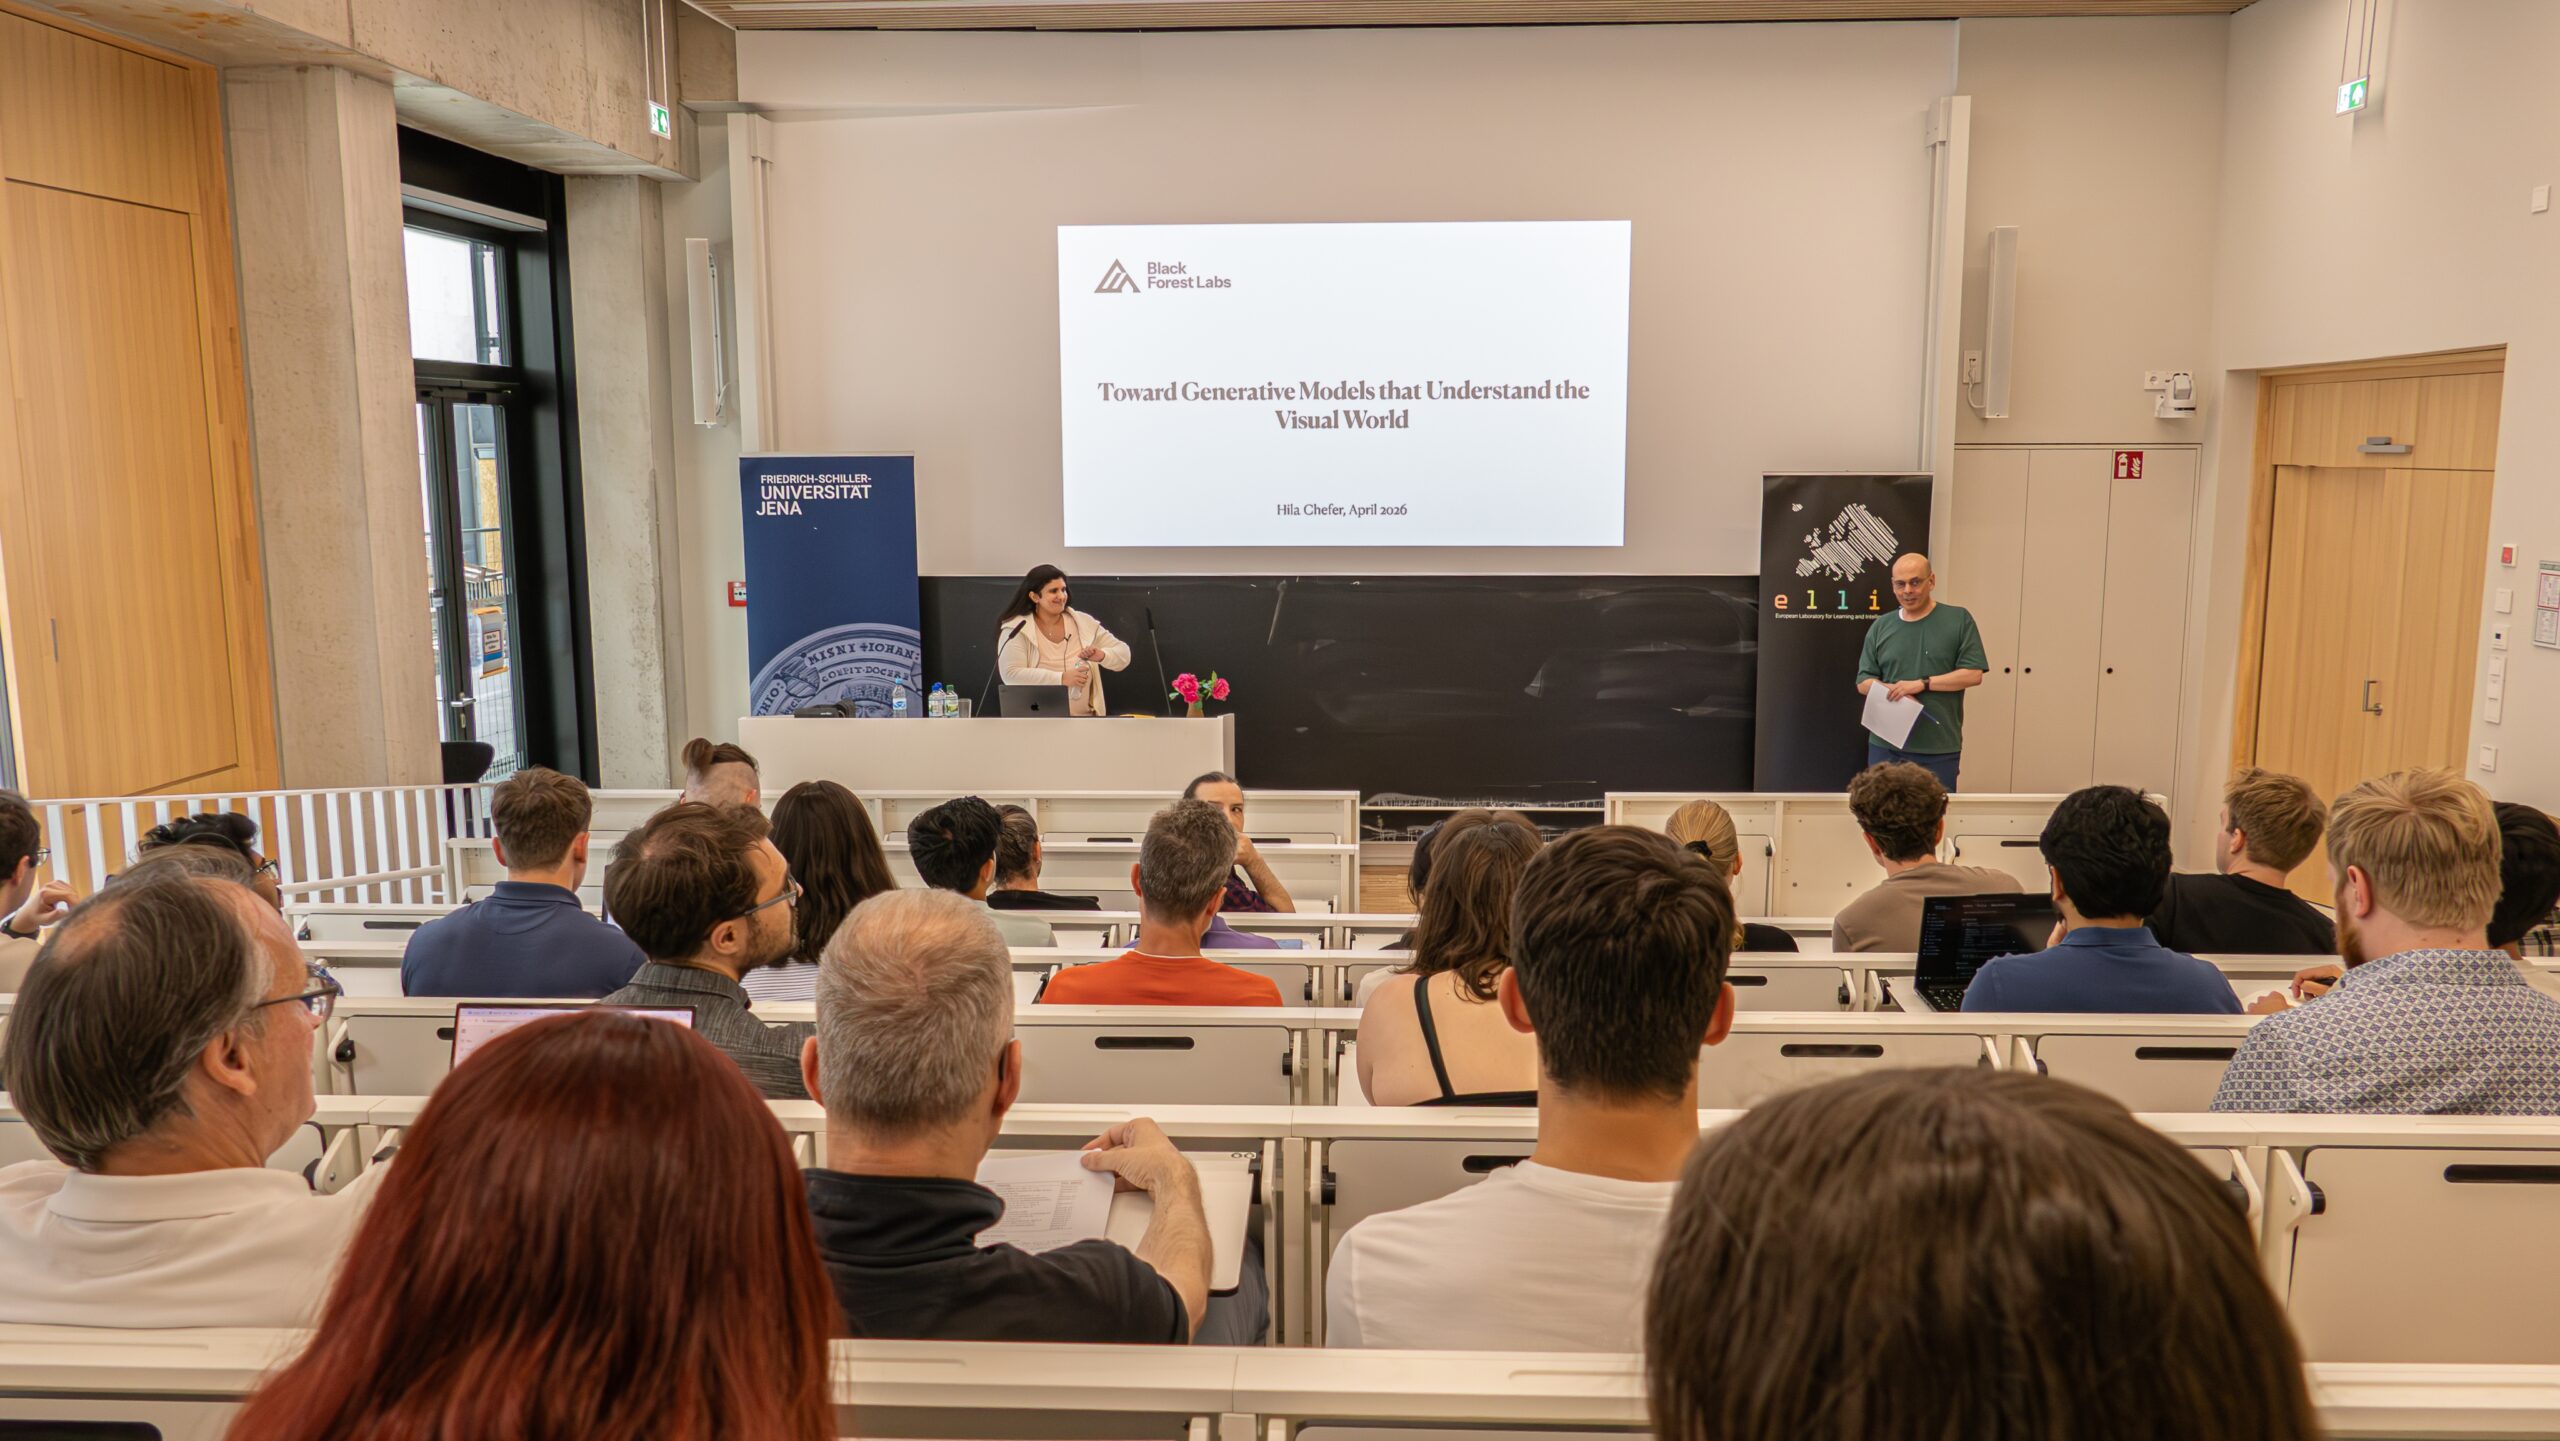
Dr. Hila Chefer
Tel Aviv University
LECTURE DATE & TIME
June 1, 2026, 14:00 – 15:00 CEST
LOCATION
Friedrich Schiller University Jena, Inselplatz 5, 07743 Jena
Letcure Hall, Room 005
TITLE
Toward Generative Models that Understand the Visual World
ABSTRACT
Despite remarkable advances, visual generative models are still far from faithfully modeling the world, struggling with fundamental aspects such as spatial relations, physics, motion, and dynamic interactions.
In this talk, I present a line of work that tackles these challenges, based on a deep understanding of the inner mechanisms that drive models. I will begin by analyzing state-of-the-art visual generators, gaining insights into the underlying reasons for their limited understanding. Building upon these insights, I will demonstrate methods that significantly enhance both spatial and temporal reasoning in image and video generation, surpassing even resource-intensive proprietary models without relying on additional data or model scaling. I will conclude the talk by discussing open challenges and future directions for advancing faithful world modeling in visual generative models.
BIO
Dr. Hila Chefer is a Research Scientist at Black Forest Labs and an incoming Assistant Professor (Senior Lecturer) at Tel Aviv University. Her research focuses on architecture development and interpretability for visual foundation models, aiming to both understand and advance their generative capabilities.
Hila earned her PhD from Tel Aviv University under the supervision of Prof. Lior Wolf, where she developed the de facto leading methods for Transformer interpretability and the Attend-and-Excite framework for text-to-image control. Her work in video generation includes the development of Lumiere (a foundational video generation model) during her time at Google Research, and VideoJAM (a joint appearance-motion framework for motion and physics fidelity in video generation) at Meta AI. Her contributions have been recognized with several prestigious honors, including the Fulbright Postdoctoral Fellowship, the Eric and Wendy Schmidt Postdoctoral Award, and the Council for Higher Education (VATAT) Award for Outstanding PhD Students.
Supported by